
#Ollama.
Ollama tutorials covering local LLM deployment, model management, and running open AI models locally.
How to Run DeepSeek R1 & Llama 3.3 Locally (Ollama vs vLLM Guide)
Run DeepSeek R1 and Llama 3.3 locally with zero API costs. Compare Ollama CLI vs vLLM high-throughput OpenAI servers with GPU VRAM benchmarks.

Edge AI: Running Small Language Models on Raspberry Pi and Phones
A hands-on guide to running small language models like Gemma, Phi, and Qwen on a Raspberry Pi or phone with Ollama, GGUF quantization, and no cloud API.
How to Connect Claude Code to Ollama (Step-by-Step 2026 Guide)
Learn how to connect Claude Code CLI to free local LLMs via Ollama and LiteLLM in 3 simple steps with zero API costs, full privacy, and no credit card.
How to Install Open-WebUI with Ollama for Local AI (2026)
Step-by-step guide to installing Open-WebUI and Ollama using Docker on Ubuntu and Linux for a private, offline ChatGPT-like AI environment.

How to Run a Local LLM Without a GPU: A CPU-Only Setup Guide
Run a local LLM without a GPU. CPU-only setup with llama.cpp, Ollama or LM Studio, with RAM requirements, quantization, and real-world speed benchmarks.
Jan.ai Alternatives: Running Local LLMs Privately
A detailed comparison and setup guide of the best alternatives to Jan.ai for running large language models (LLMs) completely offline and privately on your own local hardware.
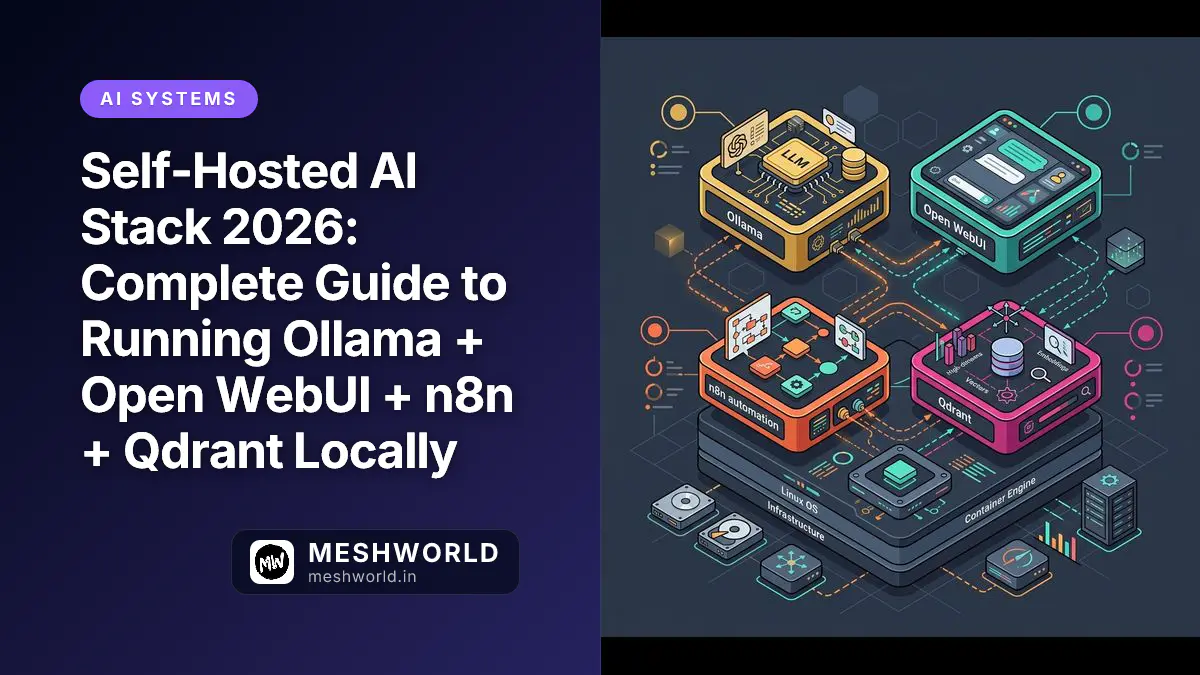
Self-Hosted AI Stack 2026: Ollama, Open WebUI, n8n & Qdrant Guide
Run a complete AI stack on your own hardware. Step-by-step guide to installing and connecting Ollama, Open WebUI, n8n, and Qdrant for a fully local AI platform.


Ollama & Local LLM Management Cheatsheet: Self-Hosted AI Guide
Master local LLM operations with Ollama. Learn core CLI commands, custom Modelfile syntax, GPU environment tuning, and REST API integrations.

Best Ollama Models to Run in 2026: Benchmarks & Recommendations
Fact-checked benchmarks of Ollama models for 2026: Llama 4 Scout/Maverick, Qwen 3, DeepSeek R1, Mistral Small 3, Gemma 4, Phi-4. Speed, quality, VRAM requirements, and best models for coding, chat, reasoning, and local RAG.
Ollama Cheat Sheet: Local LLMs, Models, API & Integration (2026)
Complete Ollama reference — pull and run local LLMs, API endpoints, Python/JS integration, multimodal models, model management, and GPU setup in 2026.
Claude Code + Ollama: Free Local AI Coding Setup (2026)
Run Claude Code with a local Ollama model instead of Anthropic's API. Step-by-step setup, recommended models, env vars, and troubleshooting.
Run Hermes Agent with Ollama: Complete Local LLM Setup
Connect Hermes Agent to Ollama for free, private AI inference. Zero API costs, complete data privacy, fast local inference.
Advanced Ollama Optimization for Hermes Agent: Speed, Cost & Quality
Squeeze 3x performance from Ollama. Optimize model selection, GPU tuning, quantization, and caching for production Hermes deployments.

Run Gemma 4 Locally with OpenClaw
Use OpenClaw with Gemma 4 26B as a local backend via Ollama — no API keys, no cloud, full privacy. Works on macOS, Linux, and Windows.
How to Use Gemma 4 with Claude Code via Ollama (April 2026)
Set up Gemma 4 locally with Ollama and wire it into Claude Code. Learn correct env vars, model tags, and context window config for April 2026.
How to Install Gemma 4 Locally with Ollama (2026 Guide)
Run Google's Gemma 4 locally with Ollama. Setup guide for E2B, E4B, 12B, 26B MoE, and 31B Dense models — hardware, benchmarks, APIs, and IDEs.
Qwen Coder Cheatsheet (2026 Edition): Running Local Agents
Master Alibaba's open-weights Qwen Coder models. Essential commands for Ollama integration, local execution, and private agentic workflows.
How to Install Ollama and Run LLMs Locally
Ollama lets you run large language models on your own machine. Learn how to install it, download models, and run them locally without any API keys.
Related Topics
Discover more topics that complement what you've been reading about.